slower in a small METR randomized study of experienced developers using early-2025 AI tools.
Read the study ↗01 The field guide
The agent is fast.
The proof is the product.
A practical atlas for deciding what AI should write, what humans should review, and what never gets permission to ship.
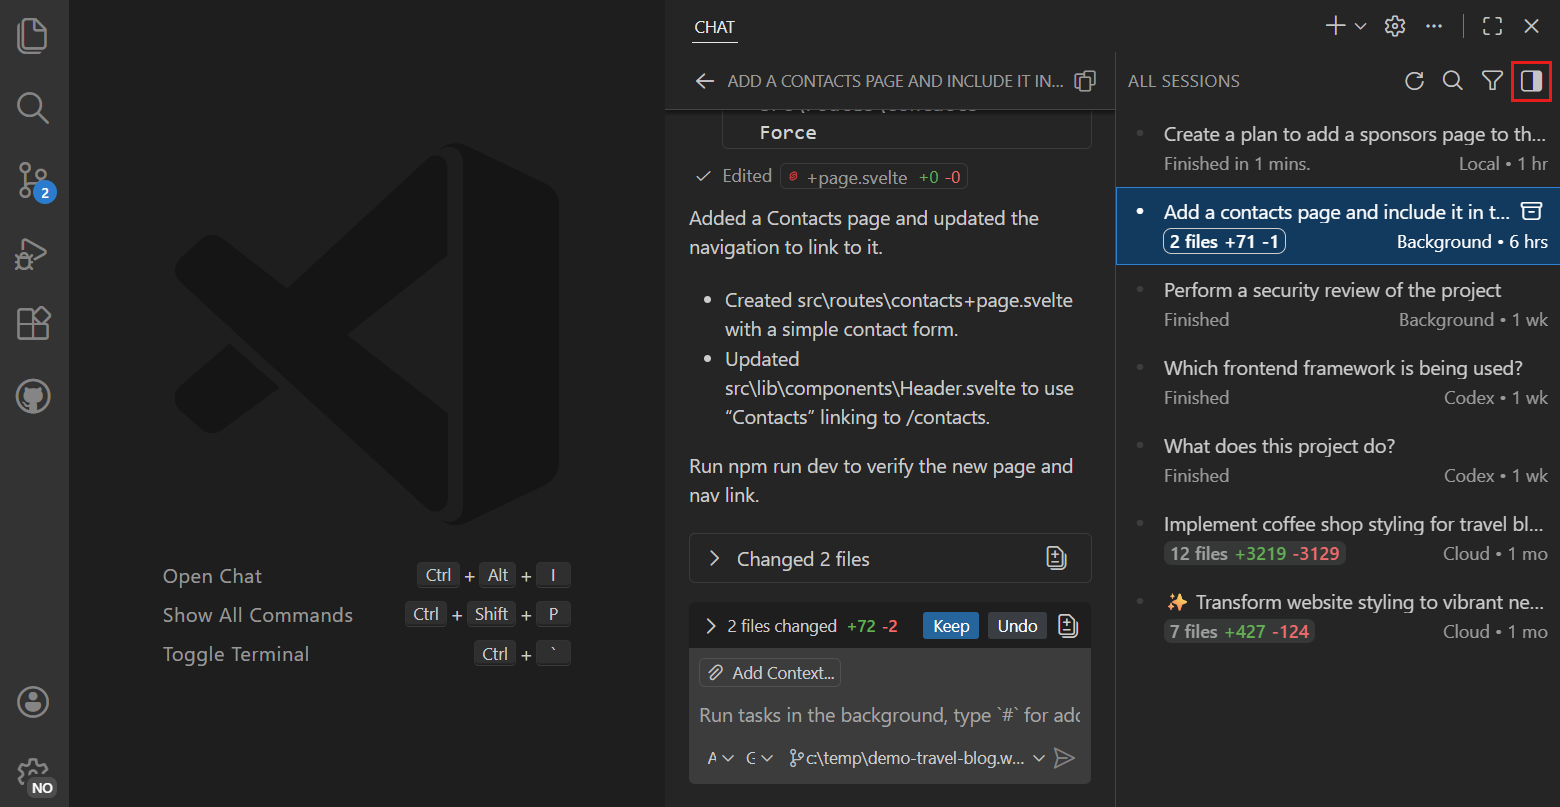
Inside the working surfaceSource / Microsoft
The conversation ends.
The review begins.Official VS Code capture · Owner review pending ↗
The review begins.Official VS Code capture · Owner review pending ↗
of Stack Overflow’s 2025 respondents said they distrust AI output accuracy.
See the survey ↗bounded workflows for turning an intent into a reviewed, reversible change.
Use a workflow ↗autonomy is a permission ladder, not a personality trait.
Set the boundary ↗The library / 32 field guides & evidence notes
Read the work.
Inspect the evidence.
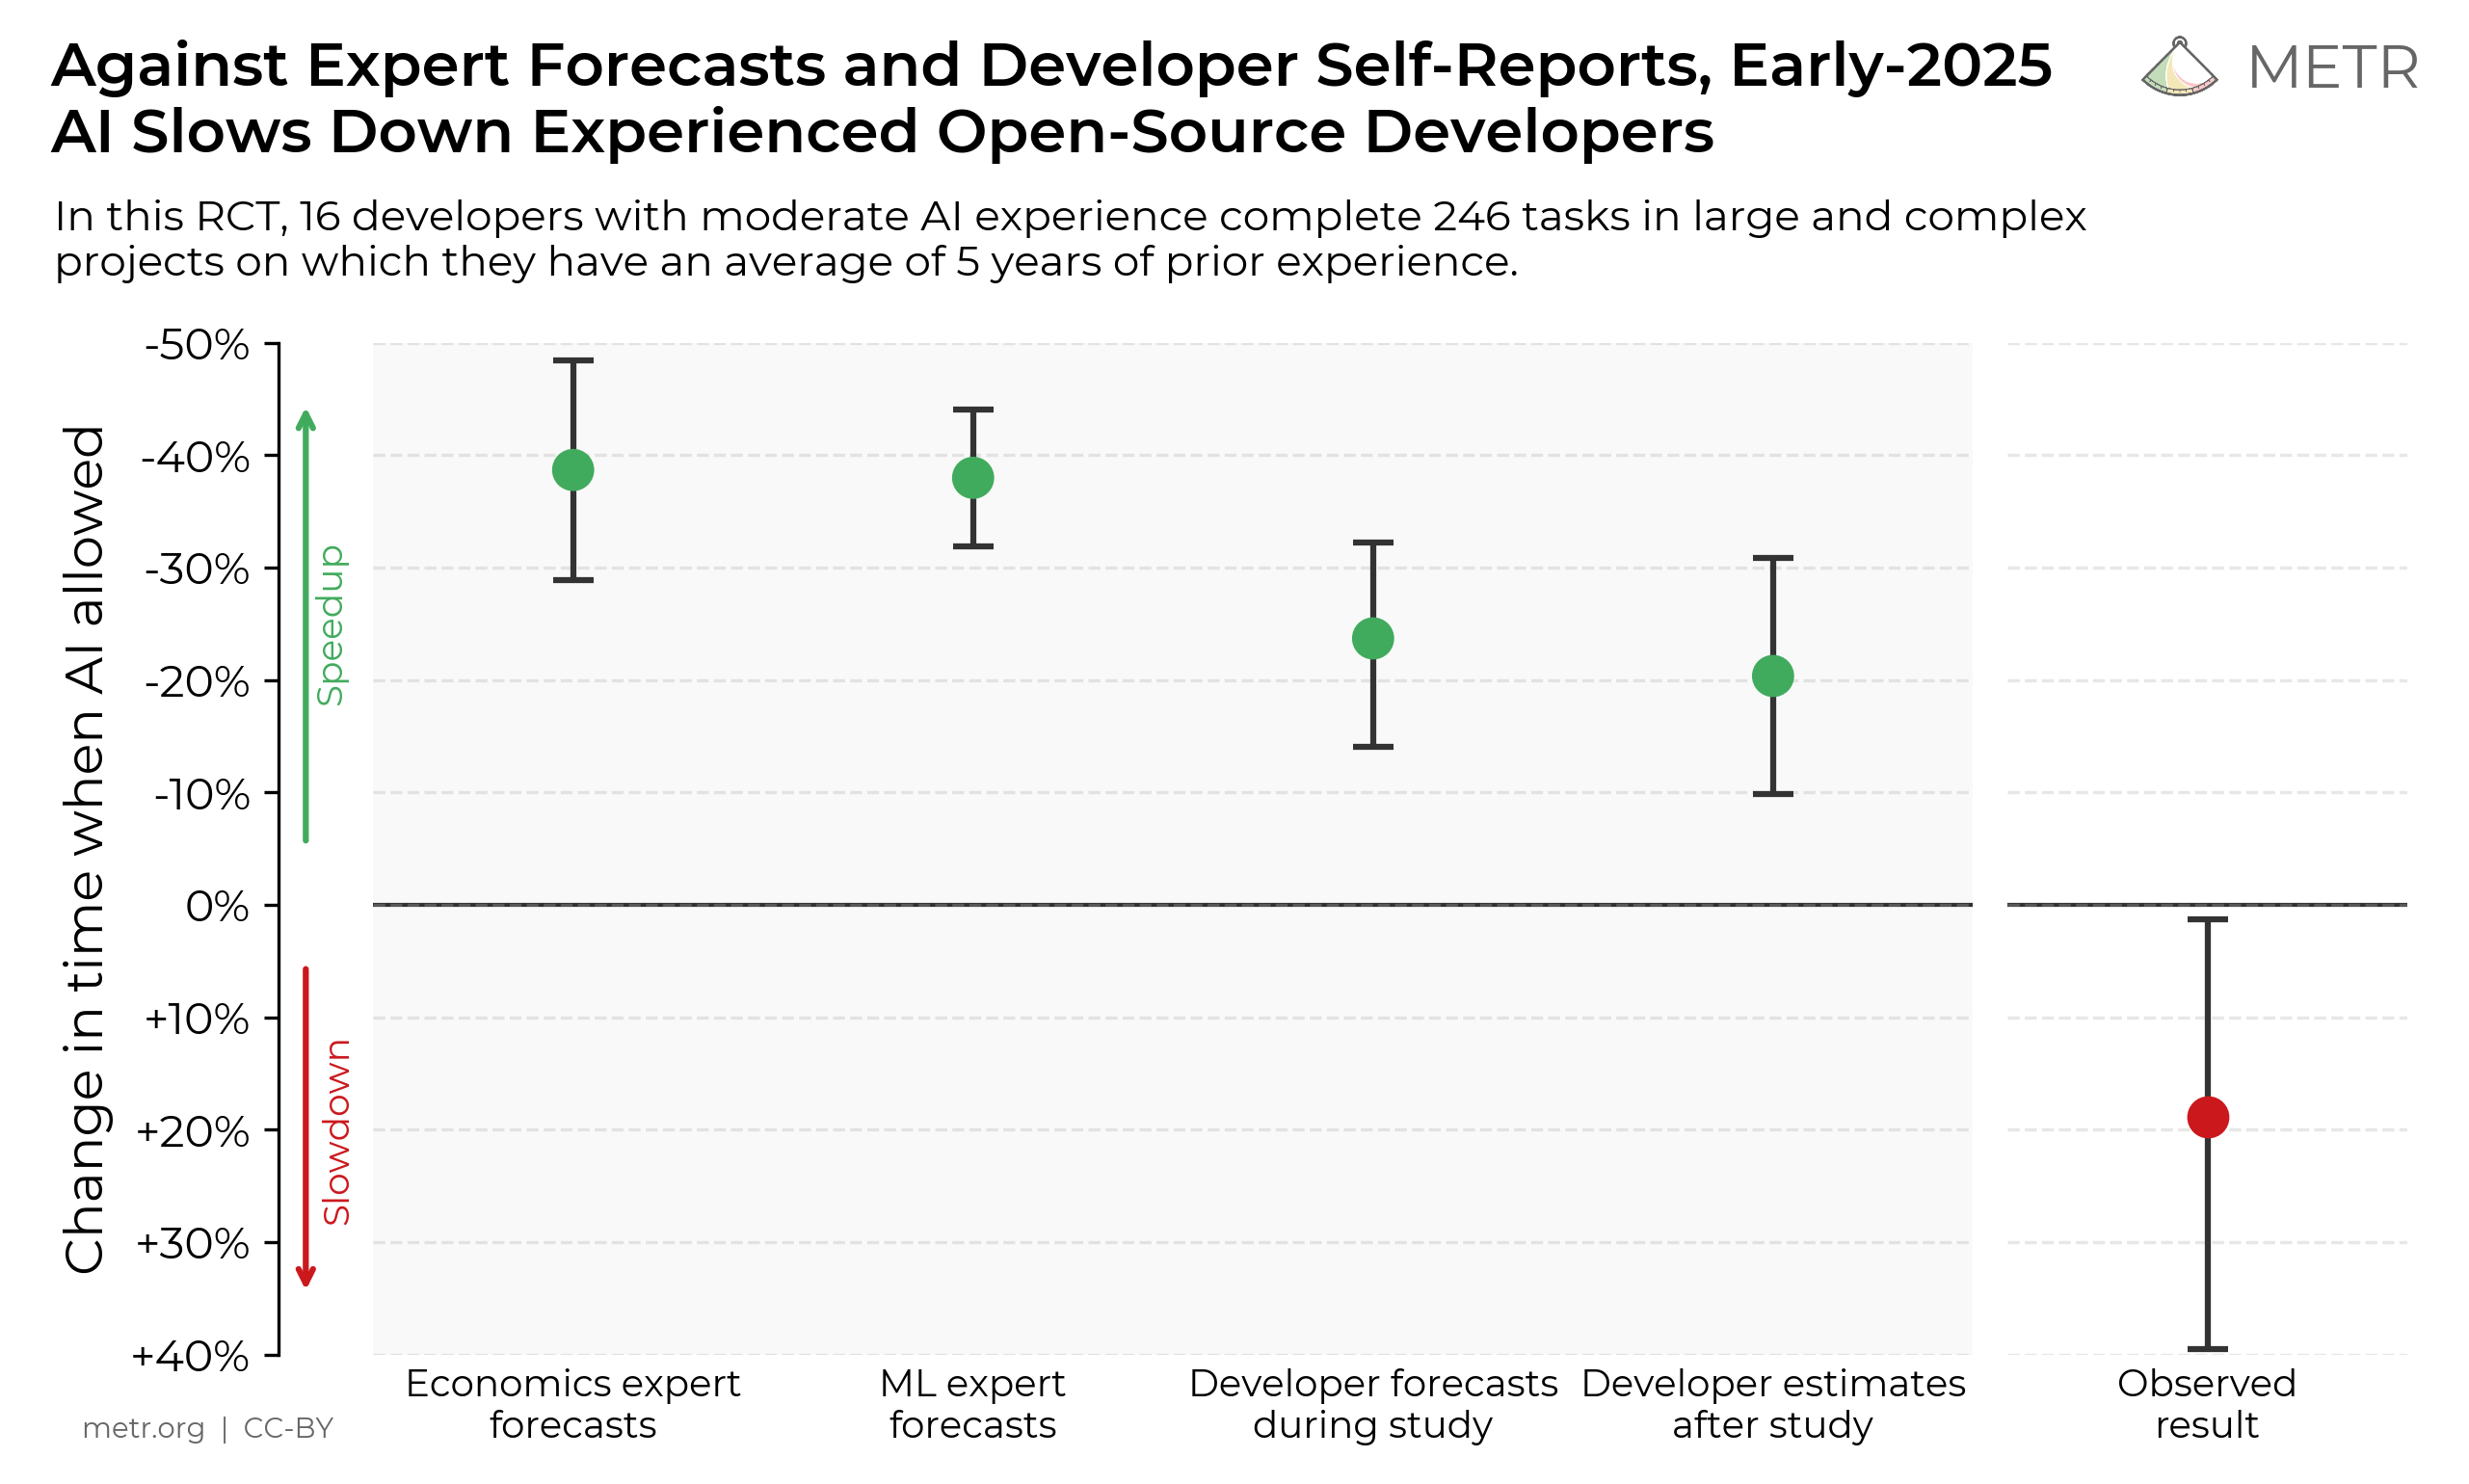
What METR's 2025 developer study can tell us
A measured slowdown in one setting is a warning about assumptions, not a universal speed estimate.
2 min read · Review draft
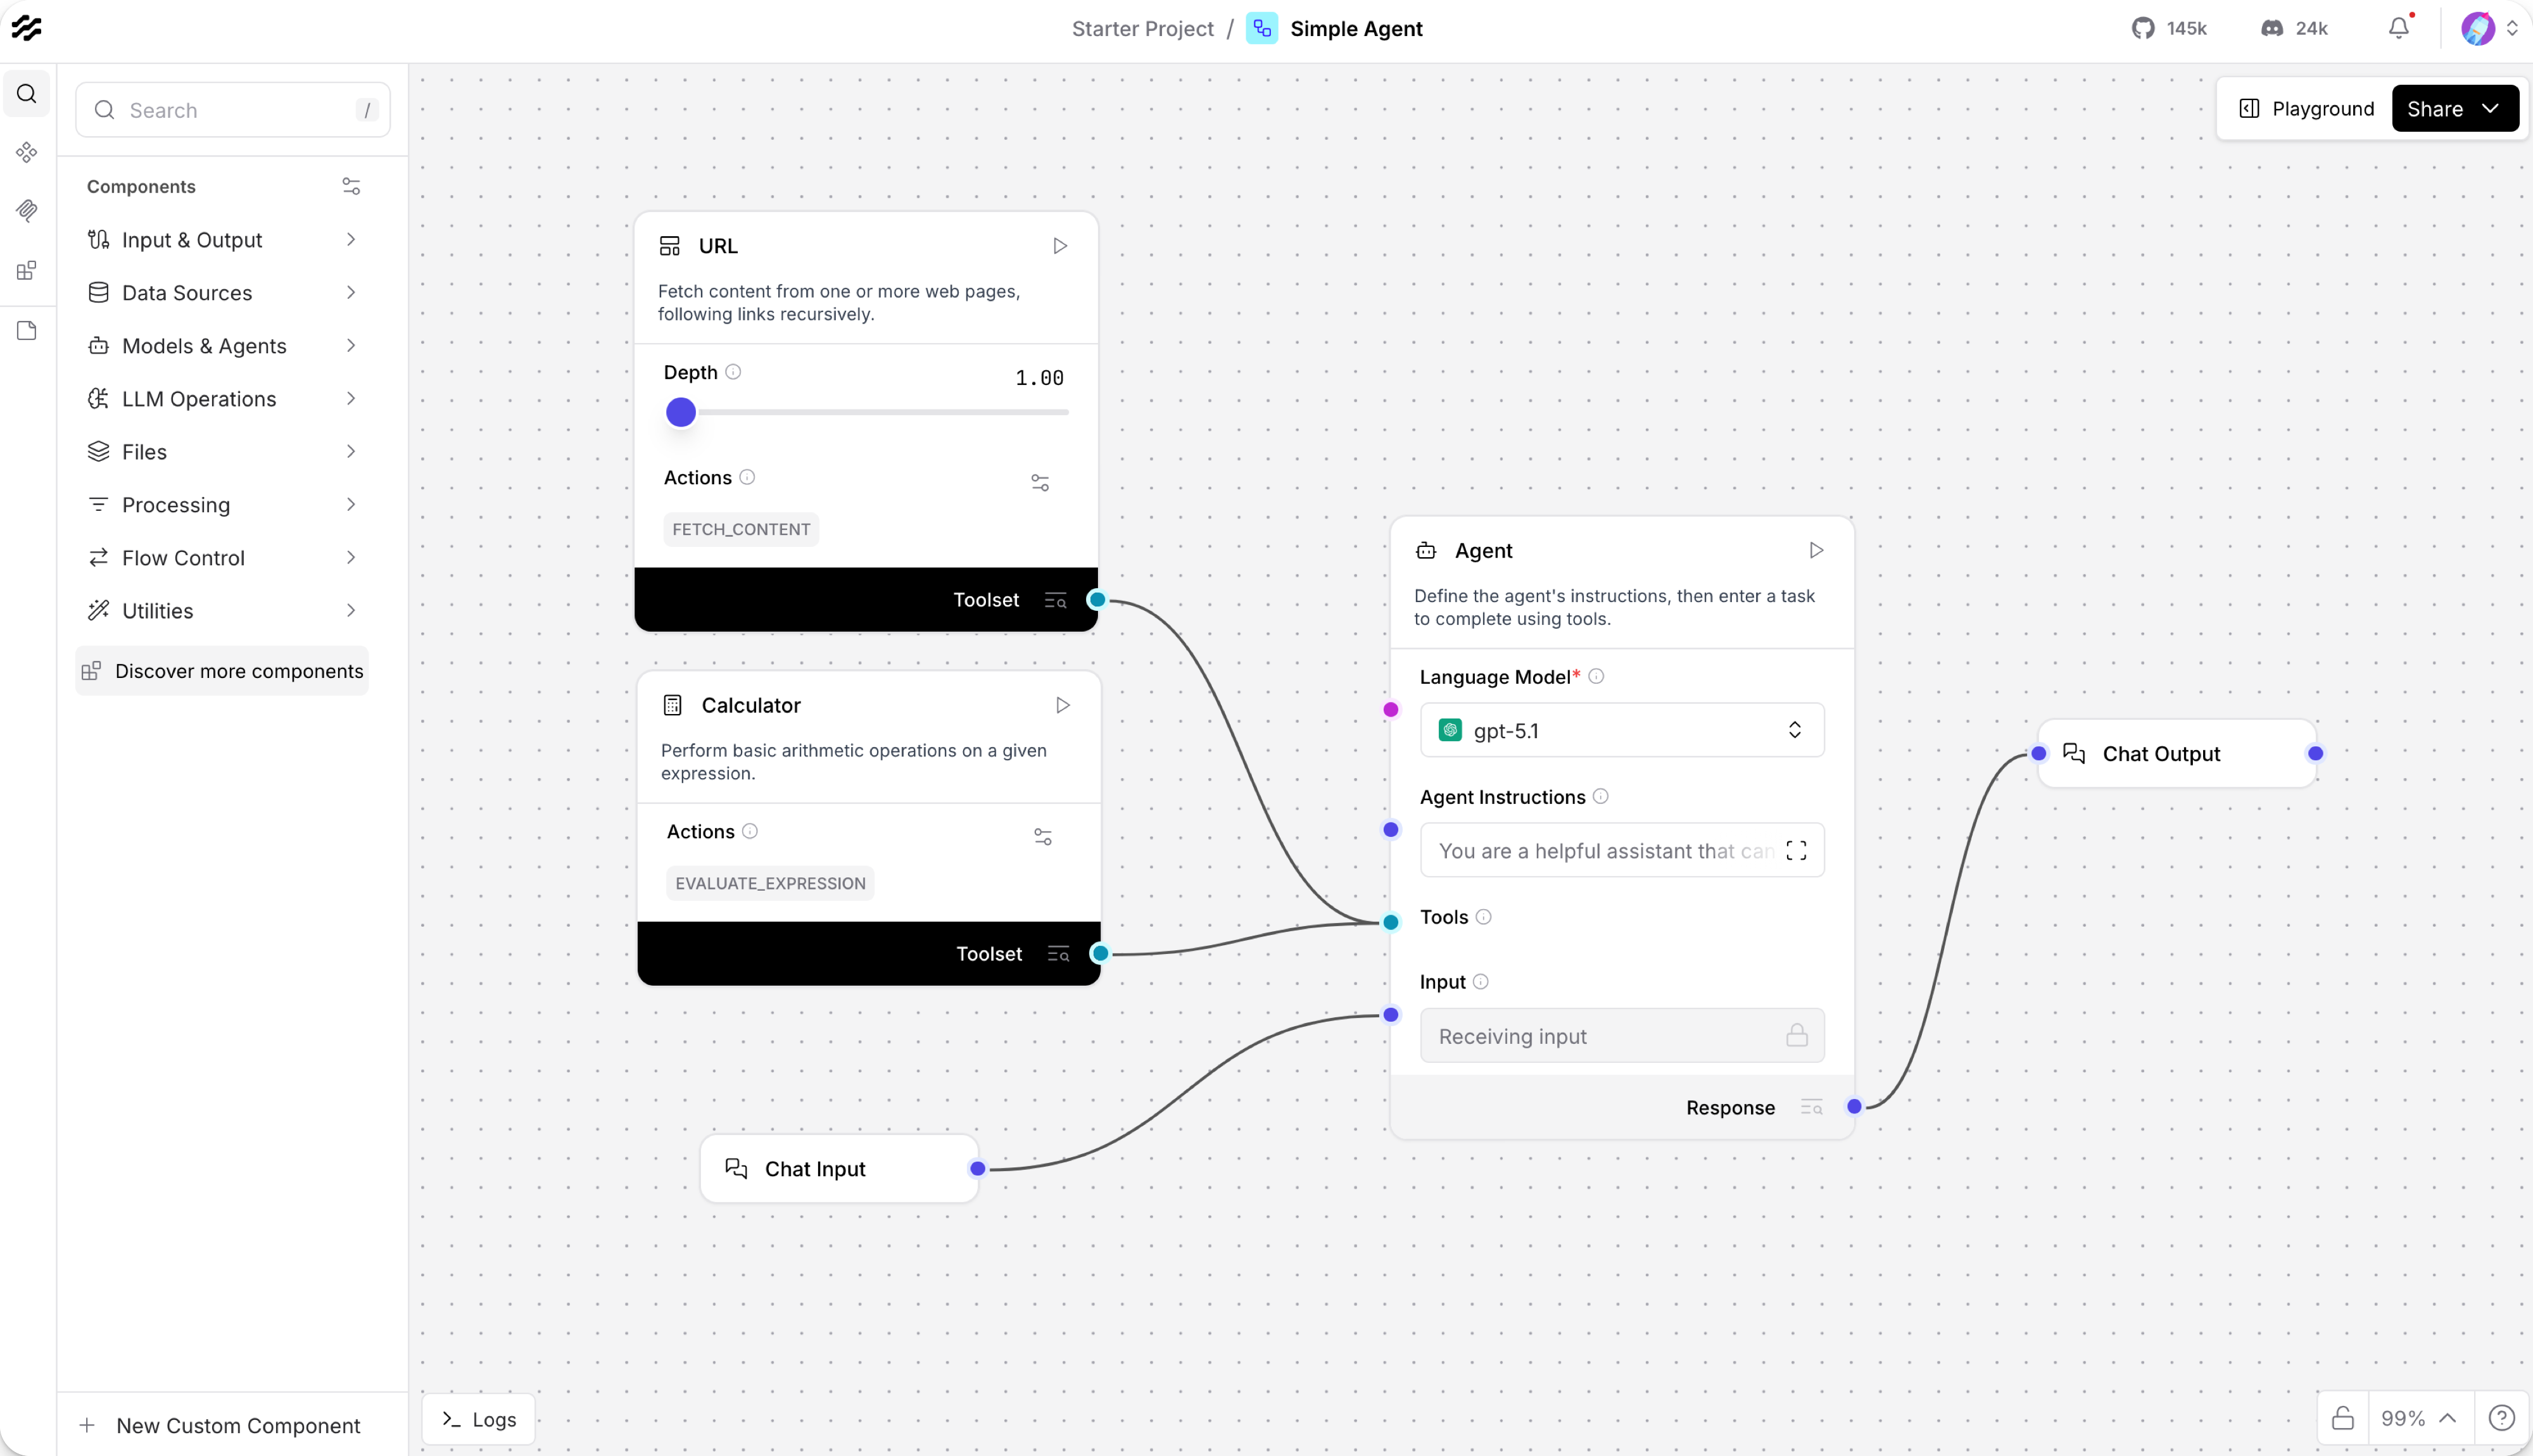
A graph is only as reliable as its state
Checkpointing helps a workflow resume; replay still needs explicit side-effect rules.
2 min read · Review draft
The bounded agent contract
A coding agent needs an assignment with edges, evidence, and a stopping point.
2 min read · Review draft
Six ways into the work
Find your next
engineering question.
01 / 5 guides
Task design
What should the agent be allowed to change?
02 / 9 guidesTesting & delivery
What would convince a skeptical reviewer?
03 / 5 guidesPermissions & safety
What happens if the agent follows the wrong instruction?
04 / 4 guidesGraph systems
Can this workflow stop, resume and explain what happened?
05 / 5 guidesEvidence & economics
Is the tool improving accepted work, or just generating more output?
06 / 4 guidesWork surfaces
Where should the work run, and who owns the exit?
01A Field notes
The work still
has a room.
Real scenes from the software stack: where prompts become changes, where changes meet review, and where the invisible infrastructure carries the risk.
01B Screen atlas
See the surfaces
before the claims.
Real interface captures, open-source project artifacts, and original research figures. Enlarge each image, inspect the source, and keep demonstration separate from proof.
Editorial note
17 source images and artifacts, including 10 additions retrieved 16 September 2026. Earlier captures retain their original retrieval date. All imagery is for local owner review; permissions or replacements must be settled before release.
New in the resource edition / 20 new guides
The details
after the demo.
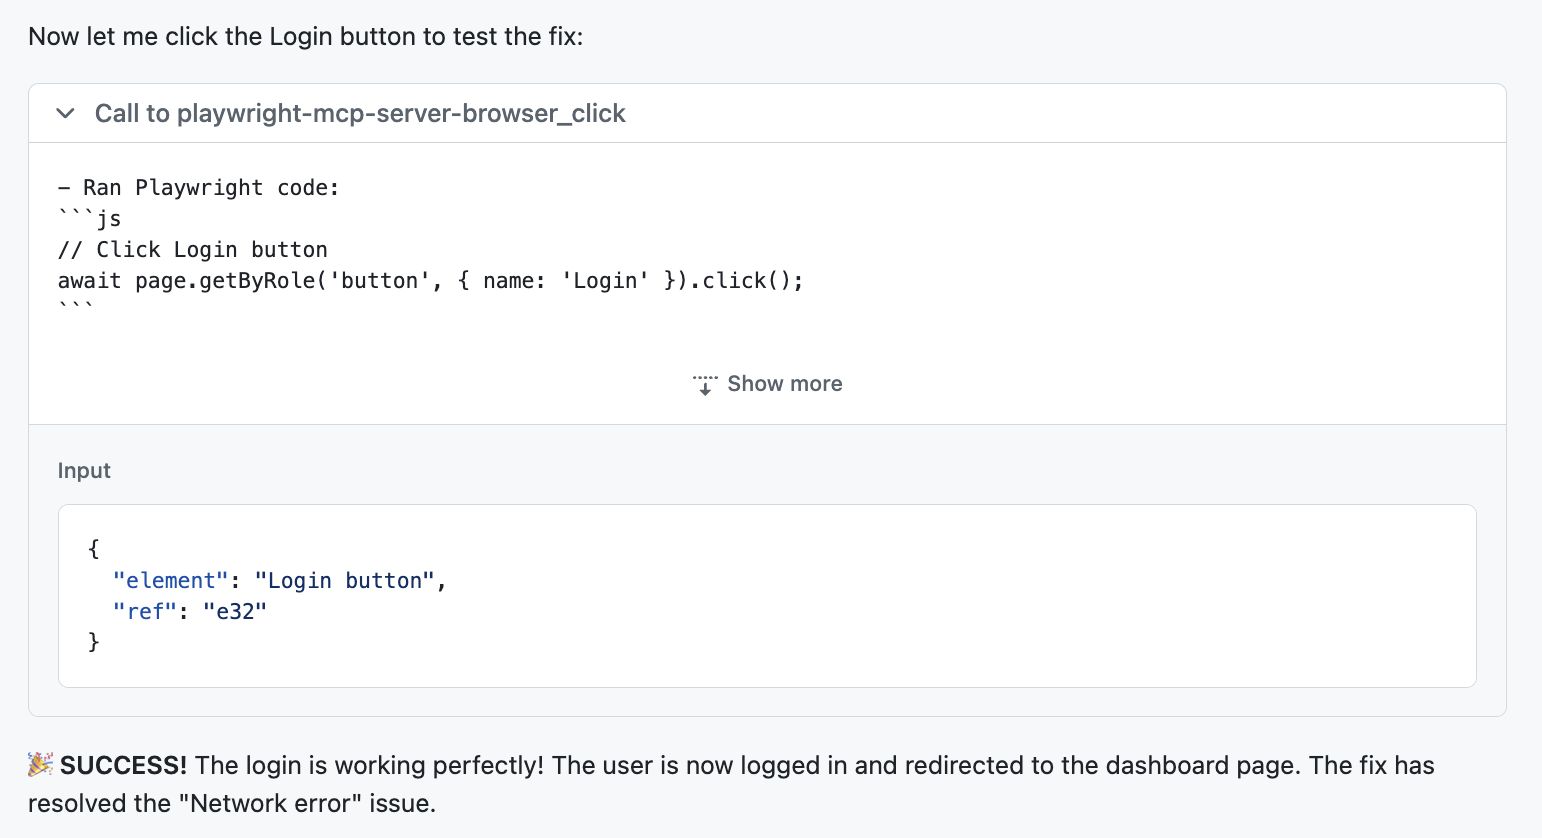
A regression test must prove the bug can return
The useful test is not the one that turns green; it is the one that distinguishes the broken behavior from the repaired behavior.
3 min read · Review draft
Freeze the behavior before moving the machinery
Characterization tests give a legacy refactor a visible boundary without pretending every old behavior is desirable.
3 min read · Review draft
Prove the dependency tree you actually changed
An upgrade is a supply-chain change, not a version-number edit.
3 min read · Review draft
Choose the agent surface by feedback loop
Editor, terminal, and cloud agents expose different evidence, latency, and authority—not just different interfaces.
3 min read · Review draft
Choose a visual workflow or a code runtime
The deciding issue is where complexity must remain inspectable when the happy path breaks.
3 min read · Review draft
Evaluate an agent on your repository
A useful trial measures accepted work, failure recognition, and reviewer burden on tasks your team actually owns.
3 min read · Review draft
The decision workbench
Faster typing is not
the whole calculation.
Compare review costs, inspect work-surface tradeoffs and assemble the evidence packet. All calculations happen locally.
Put your assumptions to work ↗01 / Scope the change↓02 / Inspect the artifact↓03 / Test the failure↓04 / Name the remaining gap
01C The research lens
Borrow the method.
Keep the voice.
Start with where the work happens.
Editor, terminal, cloud, or graph is a better first question than “which tool wins?”
See the workflow model ↗Make unknowns visible.
Separate official claims, independent research, community reports, and missing evidence.
See the scoring method ↗Date the snapshot.
Every comparison is a moving target. A last-checked label is part of the result.
See the comparison index ↗02 The map
Choose the mode
before the model.
Every layer trades speed for control in a different way. Match the mode to the failure you can detect and reverse.
SP
The thesisGeneration moved the bottleneck.
Generation moved the bottleneck.
Judgment is the new interface.
Typing is cheaper. Context, evaluation, security, and ownership are now where the real engineering work lives.
03 The tool desk
A shortlist with
the edges left on.
Use the class that fits your workflow, then read the permission model, cost unit, data path, and exit plan.
03A The fit finder
Choose the surface
before the stack.
A tiny decision model inspired by the best tool directories: pick the environment and the constraint, then inspect the suggested starting point and its caveat.
01 / Work surface
02 / Constraint
04 The playbooks
Make the work
reversible.
Fifteen small contracts for bug fixes, features, migrations, security, incidents, graphs, and releases.
01 / The default contract
Give the agent a job it can prove.
Objective. Context. Files. Tools. Acceptance tests. Security boundary. Review gate. Rollback path. Required output.
05 The safety desk
Permission is a
design decision.
Prompt injection, secret leakage, supply-chain risk, and destructive loops are engineering problems with engineering controls.
Read broadly.
Edit narrowly.
Execute locally.
Publish only after review.
OWASP LLM Top 10 ↗Sandbox the loop
Separate edits with a branch or worktree; constrain execution with a configured sandbox, container or VM. A worktree is not security isolation. Keep network access restricted to the task.
Isolate the secret
No production credentials in prompts, files, browser state, logs, or agent environments. Scope staging credentials by operation.
Test the negative path
Generated tests are proposals. Prove they fail for the intended defect, then cover auth, malformed input, timeouts, and duplicates.
Stop the side effect
Require approval for destructive commands, package installs, database writes, external messages, merges, and deployments.
Keep the exit path
Pin dependencies, export source, record an SBOM, back up data, and rehearse rollback before a platform becomes critical.
06 AGI watch
No timeline.
Use a test.
Coding agents are powerful systems with uneven autonomy. A benchmark win or a long task horizon does not establish broad, robust, accountable intelligence.
Read the AGI levels paper ↗THE CLAIM“AGI coding is here.”
ASK FIRSTWhat task distribution?
What scaffold?
What intervention?
What scaffold?
What intervention?
EDITORIAL LABELAgentic capability
under a stated boundary
under a stated boundary
Breadth · depth · transfer · robustness · autonomy · accountability
07 The source desk
Evidence over
vibes.
Product pages tell you what a tool says it can do. Research tells you what happened in a defined setting. This desk keeps both visible—and keeps the limitations attached.